Generative AI voices, built by the team behind Mozilla's open speech stack.
Coqui built generative AI voice technology, letting creatives in games, audio post-production, and dubbing create, clone, and direct AI voices with full control over performance nuance, positioned as "Photoshop for voice."
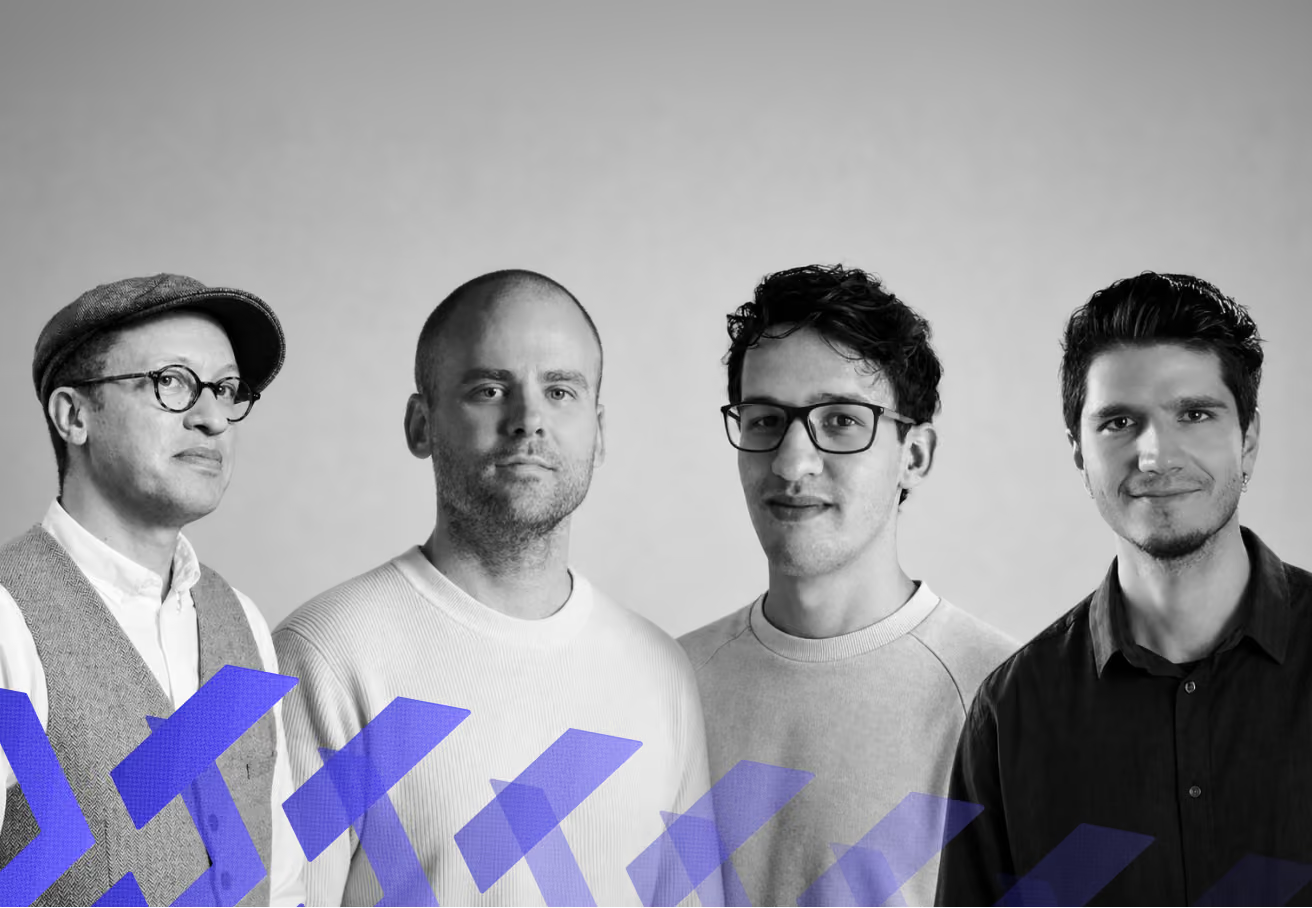
Coqui was founded in 2021 by CEO Kelly Davis, alongside Eren Gölge, Josh Meyer, and Reuben Morais. The four founders previously led Mozilla's Machine Learning Group, where they built some of the most influential open-source speech technologies, including DeepSpeech, Common Voice, and Mozilla TTS. They spun out Coqui in 2021 to bring that expertise into a dedicated company focused on building the open voice AI stack.
The team had spent years building open-source speech technology at Mozilla and understood, better than almost anyone, why existing approaches to voice creation and control were falling short for creators. At the same time, voice was emerging as one of the next major AI platforms, with production-grade speech models unlocking entirely new applications across customer support, content creation, gaming, and enterprise software. Their open-source models (YourTTS, XTTS) set real benchmarks in the field before the company layered a commercial product on top.